AI ENGINEER / AI SOLUTIONS ARCHITECT

Making AI work.
From model
to system.

AI가 실제로
작동하는
시스템을 만듭니다.

I’m Sunghoon Baek. I build AI systems from design through deployment, connecting models, data, and the infrastructure they run on.

백성훈입니다. 설계부터 배포까지 모델, 데이터, 인프라를 연결해 실제로 작동하는 AI 시스템을 만듭니다.

Currently focused on large-model compression, local inference, and engineering with coding agents.

최근에는 대규모 모델 압축, 로컬 추론, 코딩 에이전트를 활용한 엔지니어링에 집중하고 있습니다.

AI & data projects since 2019 · Based in Korea

01 / SELECTED OPEN WORK

Models, runtimes, and the work between.

모델과 런타임, 그리고 그 사이의 엔지니어링.

All projects ↗
DWARFSTARRust host
Native execution.
Inference engine · v0.1.3

ds4-dfm-rs

A Rust host for model serving, sessions, and scheduling, paired with native C/CUDA/Metal execution.

모델 서빙·세션·스케줄링을 담당하는 Rust 호스트와 네이티브 C/CUDA/Metal 실행 엔진.
Read case ↗
MEMORY-AWARE INFERENCE128 GB device.
51.2B on SSD.
Model engineering · SSD-PLE

Qwen on a single DGX Spark

Moving a 51.2B-parameter embedding table to SSD makes room for compute weights and runtime state.

51.2B 파라미터 임베딩 테이블을 SSD로 옮겨 연산 가중치와 런타임 메모리를 확보했습니다.

Read case ↗
LARGE MODELS, SMALLER FOOTPRINTPrune. Merge.
Quantize.
Model compression · REAP / REAM

From expert pruning to mixed quant

Pruning, merging, healing, and role-based precision allocation for large MoE models on constrained hardware.

제약된 하드웨어에서 대규모 MoE를 활용하기 위한 프루닝·병합·healing·텐서 역할별 정밀도 설계.

Read case ↗

QWEN / THE OPTIMIZATION WORK

Making local
inference faster.

로컬 추론을
더 빠르게.

Starting at 145 tok/s, I worked through kernel tiling, fused operations, memory traffic, and SSD-PLE caching. Each round was measured and checked before adoption.

145 tok/s에서 출발해 커널 타일링, 연산 융합, 메모리 전송, SSD-PLE 캐시를 개선했습니다. 각 변경은 측정과 검증을 거쳐 반영했습니다.

145.02 tok/sInitial direct 8K prefill · Aug 27초기 직접 8K prefill · 8월 27일
1,761.5 tok/sLater 8K server prompt · Sep 7이후 8K 서버 프롬프트 · 9월 7일

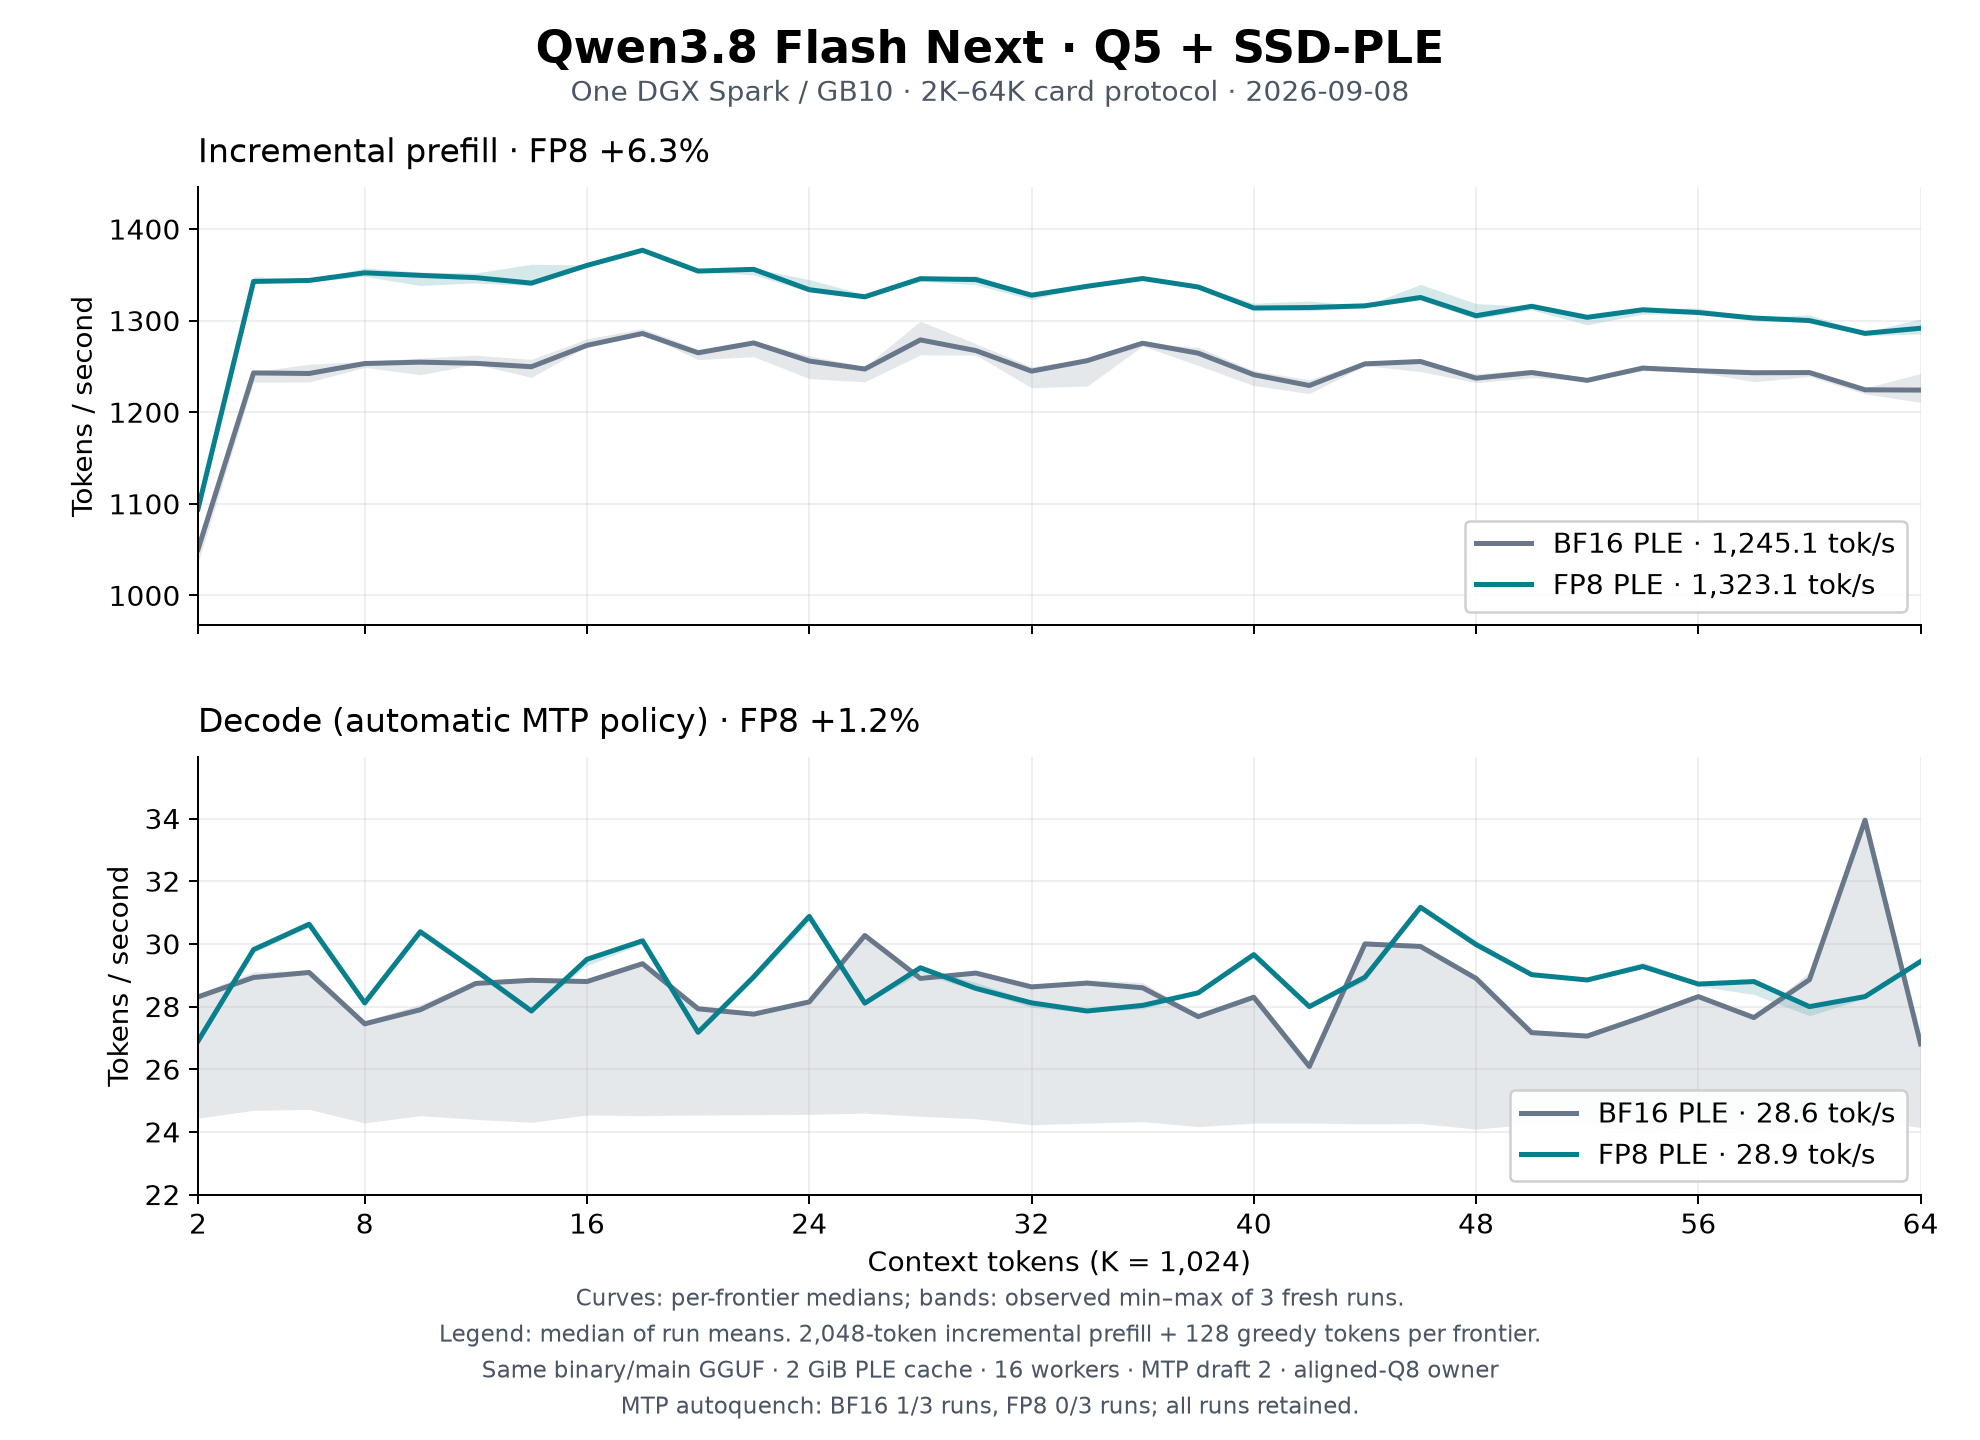
Development milestones use different protocols. The graph shows a separate, controlled BF16 / FP8 PLE comparison.

개발 시점별 측정 방식이 다릅니다. 그래프는 별도로 통제된 BF16 / FP8 PLE 비교 결과입니다.

Explore the optimization story ↗
Qwen Q5 on one DGX Spark: BF16 versus FP8 PLE over 2K–64K context. Mean prefill rises from 1,245.1 to 1,323.1 tokens per second; mean decode from 28.59 to 28.93. Bands show the observed range of three runs.
Original model-card graph · Sep 8, 2026 · Click to view full size.모델카드 원본 그래프 · 2026년 9월 8일 · 클릭하면 원본 크기로 볼 수 있습니다.Source model card ↗

02 / HUGGING FACE

Open models. Ready to inspect.

직접 확인할 수 있는 공개 모델.

Model cards include quantization recipes, runtime requirements, and measured results.

모델카드에 양자화 레시피, 실행 조건, 측정 결과를 함께 공개합니다.

Browse all 40 models ↗
GGUF / MIXED QUANT

Qwen3.8 Flash Next ↗

Q5 / Q6 compute weights · SSD-PLE · image input

Q5 / Q6 연산 가중치 · SSD-PLE · 이미지 입력

19,911max downloads in the past month한 달간 최대 다운로드 수
GGUF / MIXED QUANT

Inkling Small ↗

Diverse multimodal inputs · text · image · audio

다양한 멀티모달 입력 · 텍스트 · 이미지 · 오디오

6,955max downloads in the past month한 달간 최대 다운로드 수
GGUF / MIXED QUANT

Motif-3 ↗

Korean foundation model · gov-backed · domestic use

한국 파운데이션 모델 · 정부 지원 · 국내 도입

3,710max downloads in the past month한 달간 최대 다운로드 수

Download figures are the peak (max) last-month count recorded October 13, 2026. Each link opens the source model card.

다운로드 수는 2026년 10월 13일 기준 한 달간 최대 다운로드 수입니다. 각 링크에서 원본 모델카드를 확인할 수 있습니다.

03 / APPLIED AI

Built around real-world workflows.

현장의 워크플로를 중심으로.

Experience across satellite imagery, enterprise knowledge, education, and financial data.

위성영상, 기업 지식, 교육, 금융 데이터에서 쌓은 실무 경험.

01
TelePIX · Multimodal AI

Satellite change reporting ↗

CV detections and VLM analysis connected to evidence-grounded reports.

CV 탐지와 VLM 분석을 위치 근거가 있는 리포트로 연결.

Satellite change reporting project overview
02
TelePIX · Retrieval & RAG

Enterprise document intelligence ↗

OCR, document conversion, embeddings, and search in one ingestion workflow.

OCR·문서 변환·임베딩·검색을 통합한 인제스천 워크플로.

Enterprise document intelligence project overview
03
CREVERSE · Model adaptation

AI for English learning ↗

Domain-specific models, training-data pipelines, and model deployment.

도메인 특화 모델, 학습 데이터 파이프라인, 모델 배포.

AI for English learning project overview

HOW I WORK

Define. Build.
Measure. Repeat.

문제를 정의하고,
구현하고, 측정합니다.

I connect architecture with implementation: frame the problem, choose the data and model path, build the service, and resolve the operational issues.

문제 정의, 데이터와 모델 경로 선택, 서비스 구축, 운영 이슈 해결까지 설계와 구현을 하나의 과정으로 연결합니다.

Coding agents are part of that process. I define the tasks and acceptance criteria, direct experiments, and review evidence before keeping or releasing a change.

코딩 에이전트도 이 과정에 활용합니다. 작업 범위와 검증 기준을 정하고, 실험을 이끌며, 변경을 반영하거나 릴리즈하기 전에 근거를 검토합니다.

More about my experience ↗
Let’s build something useful.쓸모 있는 AI 시스템을 함께 만듭니다.

For engineering roles, collaboration, and technical conversations.

엔지니어링 포지션, 협업, 기술적인 대화를 기다립니다.

Get in touch ↗